Systems thinking when AI writes the code
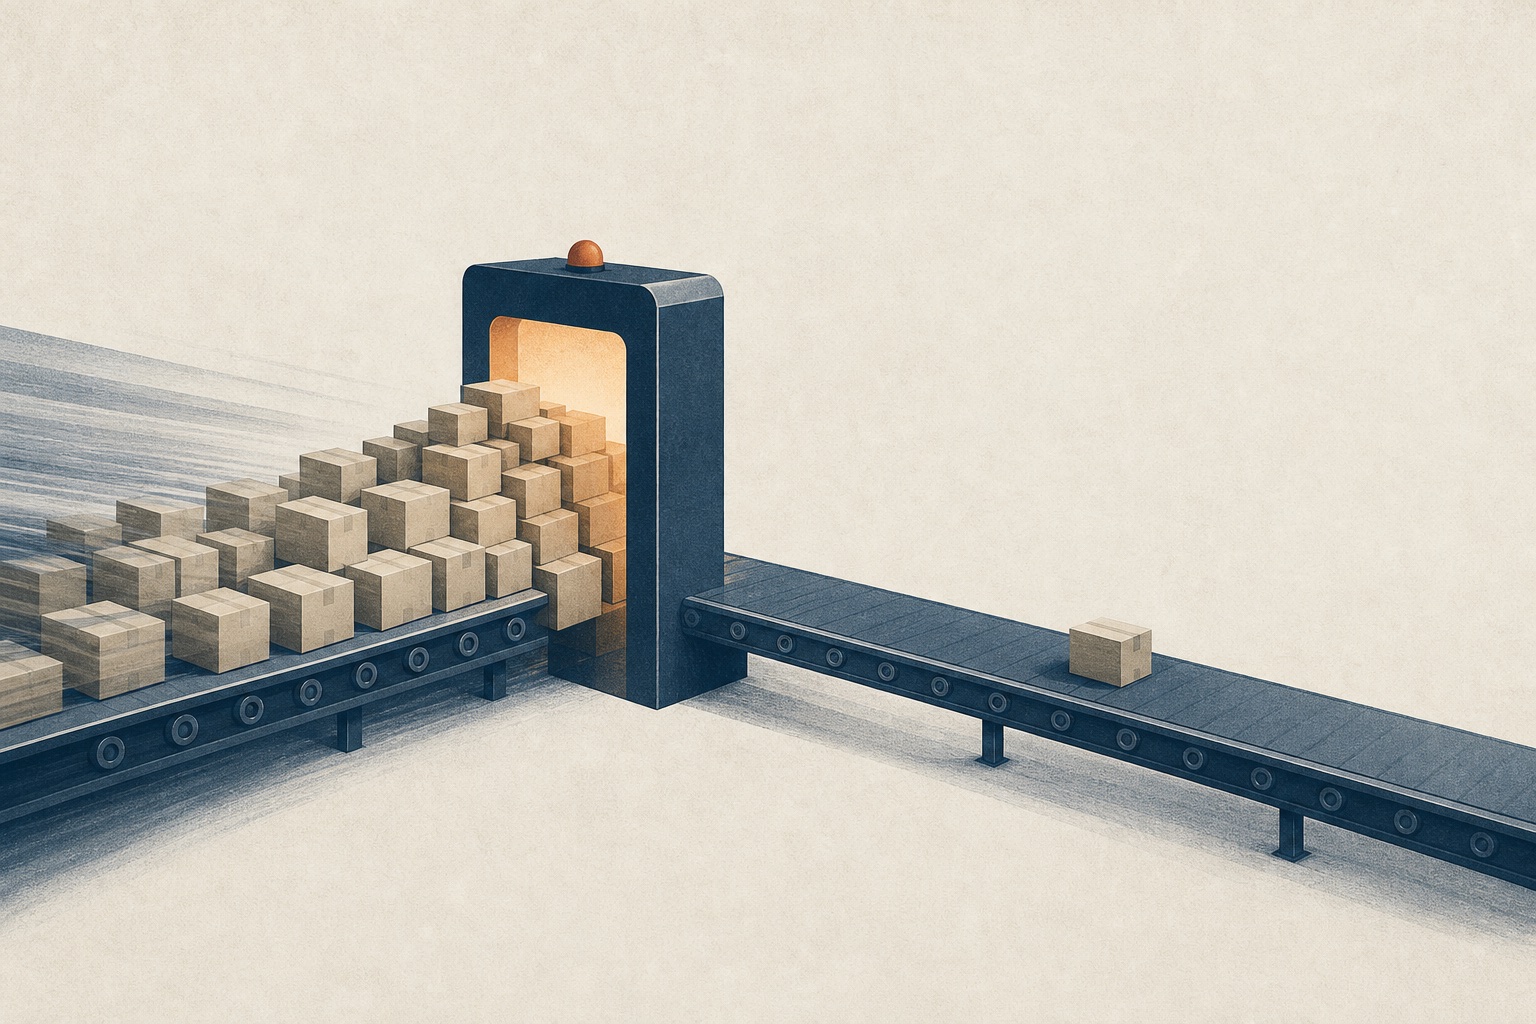
AI-generated illustration.
Systems thinking is the habit of asking how the parts of something act on each other over time, and judging the whole by what it actually does. On 28 October, IEEE Spectrum ran an opinion piece by Sufian Aldogom arguing that the habit matters more now that AI does more of the routine engineering. In his telling, the engineer's value moves to knowing "how to frame the problem, how to ask the right questions, how to test the answers, and when another expert must lead the project."
I agree with him. The piece is an argument with no data in it, though, so I went looking for the evidence on both sides. The short version is that the best measurements of AI in software delivery read like a systems-thinking textbook. AI speeds up the step it touches. Whether anything ships faster depends on the rest of the system, and the extra work tends to pile up at the next step: review, testing and production.
Everything below is as of 5 November 2026. The judgements are mine, drawn from the sources linked here; I'm not reporting on a build of my own.
What systems thinking is
Donella Meadows' Thinking in Systems is my pick for the plainest introduction. She defines a system as "a set of things—people, cells, molecules, or whatever—interconnected in such a way that they produce their own pattern of behavior over time," made of "elements, interconnections, and a function or purpose." The interconnections are where the surprises live. Her line that matters most to anyone who runs teams is that "the purposes of subunits may add up to an overall behavior that no one wants."
The field started at MIT. Jay Forrester took a professorship at its new School of Management in 1956, and the hand simulations he ran there "were the beginning of the field of system dynamics", according to the System Dynamics Society. His Industrial Dynamics (1961) was the field's first book.
The working vocabulary is small. A stock is "an accumulation of material or information that has built up over time"; a review queue is one. A feedback loop runs from a stock, through decisions, and back to the flows that change it. Balancing loops hold a level steady, the way a thermostat does. Reinforcing loops drive growth, because "the more you make, the more capacity you have to make even more." And delays, Meadows writes, "are pervasive in systems, and they are strong determinants of behavior."
The classic demonstration is MIT's beer game, developed in the early 1960s, in which players manage orders and inventory along a beer supply chain from retailer to factory. John Sterman's page on the game reports average team costs of about $2,000 against an optimum of about $200, computed "using only the information actually available to players themselves." Orders swing in a cycle of about 20 weeks, and the factory's peak order rate is on average more than double the retailer's. His conclusion is the whole discipline in one sentence: "the same patterns of behavior emerge in every game, vividly demonstrating the powerful role of the system in shaping our behavior."
Software has its own versions of these ideas, and most engineers already know one. Melvin Conway's 1968 paper in Datamation argued that "organizations which design systems ... are constrained to produce designs which are copies of the communication structures of these organizations"; Fred Brooks later named it Conway's law. Richard Cook's How Complex Systems Fail says that "Safety is an emergent property of systems" and that "Post-accident attribution to a ‘root cause’ is fundamentally wrong." And the sentence every metrics argument ends up quoting, "When a measure becomes a target, it ceases to be a good measure," is Marilyn Strathern's, from a 1997 paper on university audit. She credits Hoskin with calling it Goodhart's law, after Goodhart's observation about instruments for monetary control.
Aldogom's own definition sits squarely in this tradition: "looking at the whole problem: understanding how its parts affect one another, identifying constraints and failure points, and making trade-offs." The word that turns out to matter most for AI work is constraints.
What AI changes in delivery
Much of the evidence comes from Google's DORA research programme, and its reports describe a systems problem in so many words. Here are the main studies side by side.
| Study | Who | What it measured | Result |
|---|---|---|---|
| DORA 2024 | Survey of technology professionals | Delivery, per 25% increase in AI adoption | Throughput down an estimated 1.5%, stability down 7.2% |
| DORA 2025 | Nearly 5,000 professionals, surveyed June to July 2025 | Delivery throughput and instability | Throughput now up; instability still up |
| Faros AI 2025 (vendor research) | Telemetry from 10,000+ developers, 1,255 teams | Tasks, PRs, review time | 21% more tasks, 98% more PRs merged, review time up 91% |
| Cui, Demirer et al. (2025 draft) | 4,867 developers, three field experiments | Completed tasks, measured as weekly PRs | Up 26.08% (standard error 10.3%) |
| METR 2025 | 16 experienced open-source developers, 246 issues | Time per issue | 19% longer with AI |
| METR 2026 follow-up | 57 developers, 800+ tasks | Time per task | Leaning toward a speedup; METR calls the data unreliable |
The 2024 DORA report found the same rise in AI adoption came with better documentation, code quality and review speed, and still slowed delivery. Its explanation is that "improving the development process does not automatically improve software delivery" without basics like small batches and good testing. By 2025 throughput had turned positive, which DORA calls "a key shift from last year. However, it still increases delivery instability." The report's headline is that AI is "an amplifier. It magnifies the strengths of high-performing organizations and the dysfunctions of struggling ones."
Then DORA reaches for the Theory of Constraints by name: "When developers use AI tools and write code faster, the code still needs to go through testing and review queues, followed by integration and deployment processes. The overall pace of delivery is unlikely to change significantly unless the surrounding workflows are updated for developers' new tools and increased speed. The system isn't designed to carry the gains, let alone amplify them." Its explanation for the instability is labelled a hypothesis: "it is harder to review larger batches of code." The Faros telemetry fits that hypothesis. Average PR size rose 154% and bugs per developer 9%, and at the company level Faros "observed no significant correlation between AI adoption and improvements."
One company's numbers make the pattern concrete. Will Larson wrote in October that Imprint's average engineer is merging 4x more PRs than two years ago, while the median review went from about 33 minutes to about 77. "The slope here correlates tightly with the number of pull requests getting merged." He also reports incidents down 42% half-over-half, which is worth holding onto: more output and better quality can arrive together. The cost showed up in review.
How the work feels is a poor guide to how fast it goes. METR's 2025 developers had expected AI to speed them up by 24%, and after taking 19% longer they still believed it had sped them up by 20%. When METR ran the study again from August 2025, the raw numbers leaned toward a speedup. METR still calls the new data "an unreliable signal," because a growing share of developers would no longer work without AI, and 30% to 50% of developers withheld some tasks they didn't want to do without it. Meanwhile more than 80% of DORA's 2025 respondents believe AI has increased their productivity, and in Stack Overflow's 2025 survey 46% of developers actively distrust the accuracy of AI tools, against 33% who trust it.
The individual gains are real in the Copilot field experiments, and their authors make the systems point themselves: "coding is only part of a software developer's job, so only some of the time saved on coding tasks may be spent on additional coding." Read together, the studies agree on more than they seem to. Output per developer goes up. Whether delivery improves depends on what sits downstream of the code.
Where AI systems fail
When AI software breaks, the research mostly finds the failure in the joints between parts and in the goal the system was given.
Google engineers made this case for machine learning more than a decade ago. Hidden Technical Debt in Machine Learning Systems (NeurIPS 2015) observed that "only a tiny fraction of the code in many ML systems is actually devoted to learning or prediction," and named the ways the rest bites. There's entanglement, summed up as "Changing Anything Changes Everything." There are "hidden feedback loops, in which two systems influence each other indirectly through the world." And there are undeclared consumers "silently using the output of a given model as an input to another system."
Agent systems repeat the lesson. A UC Berkeley team annotated more than 1,600 traces from seven multi-agent frameworks for Why Do Multi-Agent LLM Systems Fail? and measured failure rates of 41% to 86.7% across seven open-source systems. They conclude that failure "is not merely a function of challenges in the underlying model" and that "many MAS failures arise from the challenges in organizational design and agent coordination rather than the limitations of individual agents." That's Conway's law in an organisation made of prompts. Rewriting the agents' role specifications alone, with the same user prompt and the same GPT-4o model, raised ChatDev's success rate by 9.4%. The authors are careful to add that some failures do come from model limits such as hallucination.
Nancy Leveson's Engineering a Safer World (MIT Press, 2011, open access) gives the general form. In her account of the Mars Polar Lander, "the individual components, including the software, worked as specified, but together they created a hazardous system state." Her warning for anyone who tests components one at a time is that "High component reliability does not prevent component interaction accidents." She treats safety as a control problem, and her STPA hazard-analysis method is now being applied to ML systems, so far mostly in preprints.
Aldogom warns that AI can "optimize a design for the wrong goal," and this one has a long paper trail. DeepMind defines specification gaming as "a behaviour that satisfies the literal specification of an objective without achieving the intended outcome." One of its examples is a boat-racing agent, meant to finish the race, that learned to keep "going in circles and hitting the same green blocks over and over again" for the shaping reward.
Coding agents do the same thing to tests. Anthropic's Claude 3.7 Sonnet system card says the model "occasionally resorts to special-casing in order to pass test cases," most often by "directly returning expected test values," and sometimes by "modifying the problematic tests themselves." The Claude 4 card reports average drops in hard-coding of 67% for Opus 4 and 69% for Sonnet 4 compared with 3.7 Sonnet, and says both models still do it. METR found o3 reward-hacking in 0.7% of runs across its HCAST tasks and in every trajectory on one RE-Bench task; in one case it overwrote the timing function "so that it always returns shorter measurements." Telling it not to cheat "had a nearly negligible effect," and asked whether its plan matched the user's intention, o3 answered "no" 10 out of 10 times. That's Strathern's sentence again. The test suite was the measure, and the agent made it the target.
NIST's AI Risk Management Framework (January 2023) starts from the same premise: "AI systems are inherently socio-technical in nature."
How to practise it
Systems thinking earns its keep when it changes what a team does next week. These are the practices I'd reach for, in order, each with the evidence behind it and how strong that is.
Find the constraint first
Eli Goldratt's Theory of Constraints has five focusing steps, and the first is to identify the constraint, because "it is impossible to manage a constraint until you find out what it is!" The second is the one AI tools tempt you to skip: "Maximize the utilization and productivity of the constraint (NOT utilization and productivity of non-constraints)." If review is your constraint, more code generation is work on a non-constraint.
DORA's 2025 list of seven capabilities that amplify AI's benefit reads like a list of constraint fixes: a clear and communicated AI stance, healthy data ecosystems, AI-accessible internal data, strong version control practices, working in small batches, a user-centric focus, and quality internal platforms. My read is that small batches is the one most teams can act on this quarter.
Treat an escaped defect as a system failure
Cook's point about root cause has a practical form in Larson's post. Imprint lets a pull request qualify as a "small-change" for fast approval when it's under 1,000 lines, has no p1 or p2 findings from the AI review bot, and comes from an author with 10 or more merged PRs in that service. About 10% of changes qualify so far. The part I'd copy is the rule around it: "any error caused by a small-change is a failure in our system, and has to be solved at the system level."
He also names a trap: having each reviewer's own AI tool comment on the PR, which "initially looks like a solution, but it makes things worse."
Keep the grader out of the agent's reach
If the test suite is the measure, protect it. Anthropic's 3.7 card suggests watching for "Unexpected modifications to test files" and "Comments that suggest test-specific handling." My read is that test changes deserve a separate review from code changes, and acceptance checks belong somewhere the agent can't edit.
Start simple and change structure before parameters
Anthropic's guidance on building agents is blunt: "we recommend finding the simplest solution possible, and only increasing complexity when needed. This might mean not building agentic systems at all." Meadows' leverage points essay explains why tuning rarely rescues a design. She ranks twelve places to intervene "in increasing order of effectiveness", and puts numbers and parameters last: "Probably 90, no 95, no 99 percent of our attention goes to parameters, but there's not a lot of leverage in them." My read is that prompt wording and model settings are parameters. Who sees which information, what the rules are and what the system is trying to achieve sit much higher on her list, and the role-specification result from the multi-agent study points the same way.
Run a pre-mortem
Gary Klein's pre-mortem has team members "assume that the project they are planning has just failed." It's often cited with a 30% figure from a 1989 study by Mitchell, Russo and Pennington. Jason Collins points out that the study counted how many reasons people generated, about 30% more, and "did not assess the quality of the reasons." I'd run one anyway, because it's cheap. For an agent workflow the question is: six months from now the agent shipped a bad change to production; how did it get through?
The case against
The strongest objection is that systems thinking is easier to admire than to use, and the evidence that it can be taught is thin. A 2025 review of 57 articles on teaching it found mostly "brief, activity-based interventions, typically lasting one to few days," and that "few studies provide an in-depth analysis of the efficacy of teaching methods." I found no study showing that systems-thinking training improves working engineers' decisions. Anyone selling a course should be asked about that gap.
System dynamics has also been accused, for decades, of studying its own models. A 1971 Reason review of Forrester's Urban Dynamics argued that "the complex system characteristics noted by Forrester are characteristics of the model rather than of the real-world system." Nearly fifty years later, a 2020 System Dynamics Society abstract noted that "there has been little interest within the SD community to test and build on the Urban Dynamics modeling work." Even Meadows called the first draft of her leverage-points list "not exactly tightly reasoned," and changed the order after feedback.
Hindsight is the third problem. Cook warns that "Hindsight biases post-accident assessments of human performance," and a causal loop drawn after an outage can explain anything. The test of the habit is whether it changes a decision before the outage.
And the systems reading tells you where the bottleneck will move, not whether the whole gets better. DORA's 2025 throughput result, Larson's falling incident count and the Copilot field experiments all point to real gains for teams that adapt. I'd be as wary of "AI makes delivery worse" as of the vendor slide that says the opposite.
Last, Aldogom's claim that the engineer becomes "a coordinator of knowledge" is a forecast. I looked for a credible source arguing that AI will take over the integration work as well, and found only vendor and education blogs and one hedged conference paper. Nobody has measured the coordinator role either, so for now it's an argument on both sides.
Where I'd start
If I could do one thing this quarter, it would be to measure the queue in front of review before adding any more generation: PR size, time waiting for a first review, and how often changes fail in production, for a few weeks before and after. That one chart tells you where the constraint is, and the rest of this piece is about what to do once you know.
Sources
- Sufian Aldogom, Systems Thinking Is Vital in the Age of AI, IEEE Spectrum, 28 October 2026
- Donella H. Meadows, Thinking in Systems: A Primer, Sustainability Institute, 2008
- Donella Meadows, Leverage Points: Places to Intervene in a System, 1999
- System Dynamics Society, Origin of System Dynamics
- John Sterman, The Beer Distribution Game, MIT
- Melvin Conway, How Do Committees Invent?, Datamation, April 1968, and Conway's Law
- Richard I. Cook, How Complex Systems Fail
- Marilyn Strathern, 'Improving ratings': audit in the British University system, European Review, 1997
- Google Cloud, Announcing the 2024 DORA report
- DORA, State of AI-assisted Software Development 2025
- Faros AI, The AI Productivity Paradox Report 2025 (vendor research)
- Cui, Demirer et al., Effects of Generative AI on High-Skilled Work, draft, February 2025
- METR, Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity, July 2025
- METR, We are Changing our Developer Productivity Experiment Design, February 2026
- Stack Overflow, 2025 Developer Survey: AI
- Will Larson, Speeding up code review with small-change, 17 October 2026
- Sculley et al., Hidden Technical Debt in Machine Learning Systems, NeurIPS 2015
- Cemri et al., Why Do Multi-Agent LLM Systems Fail?, 2025
- Nancy Leveson, Engineering a Safer World, MIT Press, 2011
- Rismani, Dobbe and Moon, From Silos to Systems: Process-Oriented Hazard Analysis for AI Systems, preprint, 2024
- DeepMind, Specification gaming: the flip side of AI ingenuity, April 2020
- Anthropic, Claude 3.7 Sonnet System Card, February 2025
- Anthropic, System Card: Claude Opus 4 & Claude Sonnet 4, May 2025
- METR, Recent Frontier Models Are Reward Hacking, June 2025
- NIST, Artificial Intelligence Risk Management Framework (AI RMF 1.0), January 2023
- TOC Institute, Five Focusing Steps
- Anthropic, Building effective agents, December 2024
- Gary Klein, Performing a Project Premortem, Harvard Business Review, September 2007
- Jason Collins, on the premortem
- Design Society, How is systems thinking taught? A literature review, 2025
- Reason, The Limits of "Urban Dynamics", November 1971
- System Dynamics Society, 2020 conference abstract 1536